
Insider Brief
- Google researchers developed Dream-RSI, a framework that uses an AI agent’s search history to improve future exploration while reducing the cost of automated discovery.
- The system tests alternative search strategies by replaying recorded outcomes, then deploys the strongest strategy without changing the underlying AI model.
- Across eight algorithm, mathematics and GPU programming tasks, Dream-RSI matched or improved on competing approaches while using fewer AI-agent calls in several tests.
In what could be a significant advance for recursive self-improvement, Google researchers report they have developed a system that allows AI agents to improve how they search for solutions by learning from earlier attempts, potentially reducing the cost of automated scientific and engineering discovery.
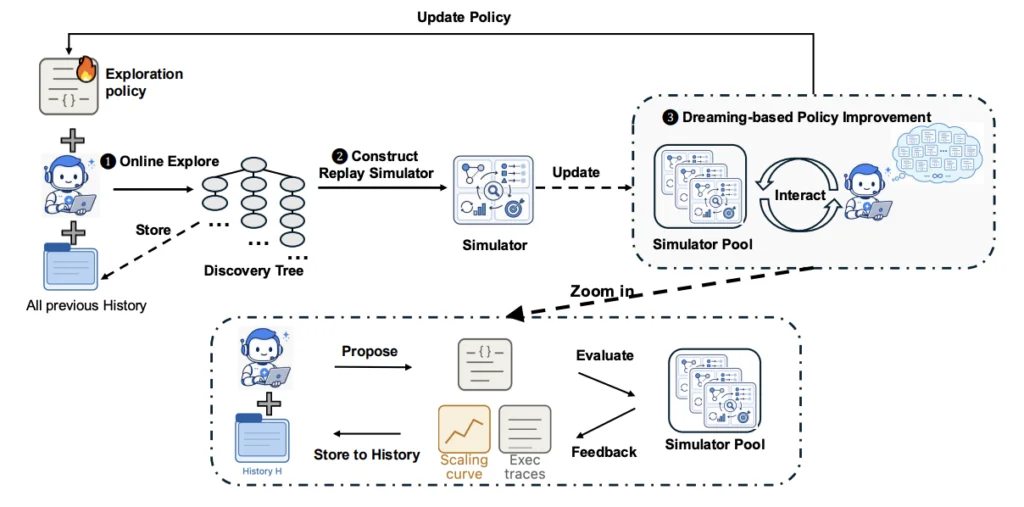
The framework, called Dream-RSI, turns records of previous searches into simulated environments where an AI agent can test alternative exploration strategies without repeating the underlying experiments. The agent can then deploy the most promising strategy during its next live search.
Recursive self-improvement, or RSI, is the ability of an AI system to repeatedly improve its own capabilities or operating methods, a potentially important development because each advance could help the system make subsequent advances faster and with less human intervention.
In Google’s tests, which spanned algorithm engineering, mathematical optimization and GPU programming, Dream-RSI matched or exceeded several competing approaches while reducing the number of AI-agent calls required to find solutions, according to a paper posted on arXiv.
The researchers describe the method as recursive self-improvement, but the system does not retrain or alter the underlying AI model. Instead, it improves the software responsible for directing the model’s search.
That distinction limits the scope of the claim while pointing to a practical way to make long-running AI discovery efforts more efficient.
Learning From Previous Searches
AI agents can search for new algorithms, mathematical constructions and computer programs by repeatedly proposing solutions, testing them and using the results to decide what to try next.
These searches can require thousands of model calls. Evaluating a new search strategy may be particularly expensive because researchers must allow it to operate across many proposal and evaluation cycles before determining whether it works.
Dream-RSI attempts to reduce that cost by recording each search as a tree, which contains the alternatives the agent explored, the order in which it explored them, the computational cost and the results of each attempt.
The system then uses that history as a replay simulator. An AI agent can test different policies for navigating the recorded tree, including which branches to pursue, how many attempts to run in parallel and when to stop searching.
Because the outcomes are already stored, the system can evaluate these policies without running the original coding agent and evaluator again. The selected policy is then used in another live search, which generates additional results and expands the history available for the next round.
One way to understand the method is to think about an explorer who records every road, wrong turn and dead end encountered during a journey. Before setting out again, the explorer can use that map to compare different routes without physically retracing each one.
Only the exploration policy changes during this process. The underlying Gemini model, evaluation system and execution tools remain fixed.
Tests Across Eight Tasks
The researchers evaluated Dream-RSI on eight tasks covering three areas. These included designing a faster statistical algorithm, solving three mathematical optimization problems and improving four GPU computing kernels.
For the algorithm-engineering test, the system searched for more efficient implementations of the Lasso regularization path, a statistical method used in areas including genomics, finance and model selection.
Using Gemini 3.1 Pro, Dream-RSI produced a solver with an average runtime of 2,931 milliseconds across six held-out datasets. A fixed exploration policy produced an average runtime of 3,587 milliseconds. Dream-RSI used 317 discovery-agent calls, compared with 550 for the fixed policy.
A version using Gemini 3.7 Flash lowered the average runtime from 2,516.7 milliseconds to 2,350.6 milliseconds while reducing agent calls from 3,200 to 1,879.
The resulting solvers also outperformed implementations from the widely used scikit-learn and glmnet software libraries across the six evaluation datasets, according to the paper.
Dream-RSI required as much as 162 times fewer agent calls than SimpleTES, another AI discovery system that used 51,200 generations. That comparison should be treated cautiously because the systems used different underlying models and experimental configurations.
On three mathematical optimization problems, Dream-RSI matched or exceeded several automated discovery systems while using fewer than 1,000 generations. It matched the strongest reported result for a circle-packing problem and produced the highest score reported in the paper’s comparison for a sum-difference problem.
Results were more mixed on an autocorrelation problem with Dream-RSI remaining competitive, but SimpleTES reporting a better result while using a substantially larger search budget.
In GPU kernel engineering, Dream-RSI reached comparable performance with 1.79 to 2.43 times fewer generations on two tasks. On two others, it produced kernels with performance scores that were 1.44 and 2.09 times higher than those found through fixed exploration under similar budgets.
A Narrower Form of Self-Improvement
The study suggests that an AI system may not need to retrain its underlying model to improve its performance. It can instead become more effective by changing how it allocates time and computing resources during a search.
The researchers also compared replay-based learning with a simpler approach that converted previous searches into written guidance for the agent. The explicit guidance consistently reduced performance in one GPU task.
The researchers indicate that high-level instructions drawn from previous attempts can constrain the agent’s search too much. Replaying the full history preserves more information about the different paths the agent could have taken.
The approach has some limitations, namely, that Dream-RSI can only replay outcomes that were recorded during earlier searches. It cannot determine what would have happened along a branch that the agent never explored.
A policy could also become overly adapted to its existing search history. The researchers partly addressed that risk by redeploying improved policies in new live searches, but the tests covered only eight structured programming and mathematical tasks.
For a deeper, more technical dive, please review the paper on arXiv. It’s important to note that arXiv is a pre-print server, which allows researchers to receive quick feedback on their work. However, it is not — nor is this article, itself — official peer-review publications. Peer-review is an important step in the scientific process to verify results.